

This was scheduled for publication on October 20. I created a placeholder on LinkedIn to accept the URL for this article after it published on Substack. LinkedIn, however, published the draft placeholder when it published “Join the Cat Side.” For an unpublished article, it’s shockingly popular. Plus, the draft has now been shared, so it’s unofficially out there. Consequently, I might as well put it officially out there, and here you go.
I had a chance to evaluate Haiqu’s circuit compression claims, and I quickly realized that comparing it to Qiskit would be insufficient. Everyone always compares everything to Qiskit. Everybody always beats Qiskit. Besides, the closest competitor for this task is QMill. You may remember QMill from “Compressing Shor’s Algorithm,” which featured Prof. Peter Shor in a corset.
The hypocritical baseline was Qiskit without optimization. That’s optimization_level=0 for those who use it. Let’s just unroll the quantum circuit, then let Haiqu and QMill have at it.
The target hardware for both was ibm_kingston, with its IBM Heron chip, and IQM Emerald. It’s worth noting that Haiqu works with specific backends, whereas QMill works with gatesets.
The outputs allow more comparisons than these, but I decided early on to focus on circuit depth and 2Q gate counts as my metrics. We’ll just count headshots and bodyshots, and then we’ll go to the judges’ scorecards.
But first, I’m hungry. Let’s eat….
Grover’s Algorithm: Qiskit Dinner Party
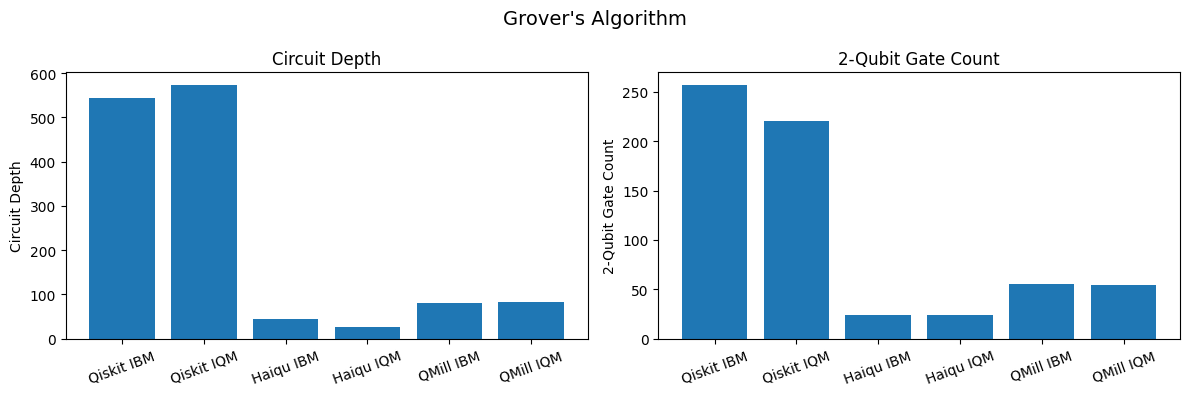
Five years ago, I learned about what IBM called “Grover’s Dinner Party.” I converted it to OpenQASM 2, I renamed it the “Qiskit Dinner Party,” and I added it to my library. I’ve been using it ever since to evaluate a non-trivial percentage of some 300+ quantum technology products. The quantum circuit is neither tiny nor massive, so I started there.
Haiqu ran for ~30 seconds, although that includes both IBM Heron and IQM Emerald. QMill uses LUMI or AWS supercomputers to compress circuits, and runtime can be set for hours. But to be “fair,” I set QMill to run for 1 minute for each backend. I also tried it for 30 minutes, but Haiqu still came out noticeably ahead on depth and 2Q counts despite consuming a fraction of the time. The results you see above used 4 QPUs for 6 hours, so increasing QMill’s iteration_time_minutes does not guarantee better results, at least not with this particular quantum circuit.
Haiqu’s compressed circuit not only simulated correctly, it also returned correct results from ibm_kingston. That’s impressive. I don’t have an AWS account with which to test it on IQM Emerald, but the simulator and IBM Heron prove that Haiqu’s circuits still work after compression.
QMill’s circuit simulated correctly. It works with IQM Resonance, IQM’s cloud, so you can use IQM Emerald for free. So, I did. The result was correct, but not as convincing as Haiqu’s execution on ibm_kingston. It’s an apples-to-oranges comparison on real hardware, but the point of this exercise, between simulation and execution on IQM Emerald, is simply to demonstrate that QMill’s circuits still work after compression.
The bottom line, because Stone Cold said so, is that Haiqu won this first battle on both circuit depth and 2Q gate counts, while also executing noticeably faster. Importantly, both Haiqu and QMill circuits not only simulated correctly, but they also returned correct results on real NISQ hardware. The latter is not a prediction I made in advance.
QMill noted that the discrepancy in circuit sizes might be due to Haiqu using approximations versus QMill being exact; therefore, I am declaring this a legitimate Round 1. I’ve used “Round 1, fight!” as a subtitle on multiple occasions, but there will be a Round 2 this time, and maybe even a Round 3. The smaller circuit doesn’t matter if it doesn’t work, so Round 1 is just verifying that the circuits haven’t been butchered in the efforts to compress them.
Quantum Phase Estimation (QPE): LiH(6)
Most of my library is QPE, courtesy of the Classiq synthesis engine. This was meant to determine how far any particular software or hardware could be pushed. Can your product handle H2 with 1 counting qubit, O2 with 6 counting qubits (the farthest I could push Classiq’s engine at the time), or somewhere in between?
“Go big or go home,” someone always says, so I started with O2, aka molecular oxygen, with 6 counting qubits:
Haiqu returned an error stating that the job exceeded the allowed time limit; however, it promised longer limits in the future. This is common, by the way, when alpha or beta testing.
QMill returned an error that I had insufficient credits to run it.
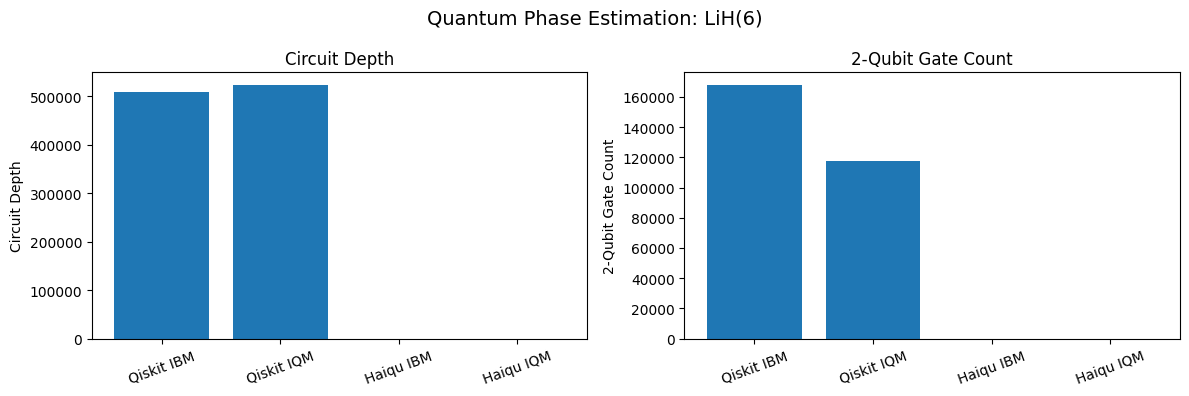
So, I downgraded a bit to LiH, aka lithium hydride, also with 6 counting qubits. Although it is still a hefty quantum circuit, it requires only about half of the code as O2 with 6 counting qubits:
Haiqu needed a little over 6 minutes to compress the circuit for both IBM and IQM backends. Haiqu’s simulation results matched Qiskit’s simulation results, albeit much faster. Haiqu’s compressed circuit also executed on ibm_kingston, showing
011111:0.8567as compared to011111:0.976with the simulator.QMill gave me additional credits by this point, and I executed it with 4 GPUs running for 6 hours on LUMI. The problem is that I can’t retrieve the results. It’ll either time out if I run it locally, or I’ll get logged out waiting for the comparison to load in the portal. They’re unable to extend that logout duration at this time.
The histograms are NOT in error, by the way. The differences between the code in my library and Haiqu’s quantum circuits are so extreme that you can’t see Haiqu’s bars on the histograms at all. And, again, I can’t stress enough that Haiqu’s compressed circuit executed well on real NISQ hardware. After evaluating 300+ quantum technology products, I very rarely say “WOW!” at this point, but that ibm_kingston result got a “WOW!” out of me.
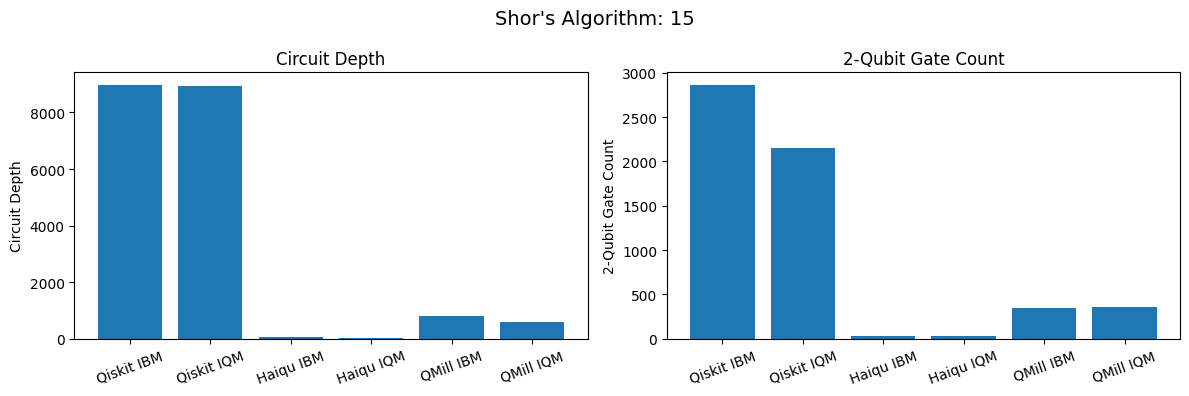
Shor’s Algorithm: Factoring 15
I’ve got more circuits in my library, but let’s face it, the granddaddy of ‘em all draws eyeballs to articles. And like most of the others, this circuit also came from the Classiq synthesis engine.
Haiqu’s circuit executed on ibm_kingston. You can see the effects of using NISQ hardware in the results, but the top 4 measurement outcomes nevertheless matched the simulator.
QMill’s circuits were larger than Haiqu’s after 4 GPUs ran for 6 hours on LUMI, and they did not execute well on IQM Emerald. There are multiple reasons why that might be the case, but it’s a moot point as long as Haiqu’s circuits are smaller and working. I exported QMill’s IBM Heron circuit for Round 2, for an apples-to-apples comparison.
This is a smaller circuit than LiH with 6 counting qubits, so you can see short little Haiqu bars this time on the histogram. And, once again, Haiqu’s circuit returned correct results on real NISQ hardware, which is astounding considering we’re talking about Shor’s algorithm, even though we’re only talking about factoring 15 at this point.
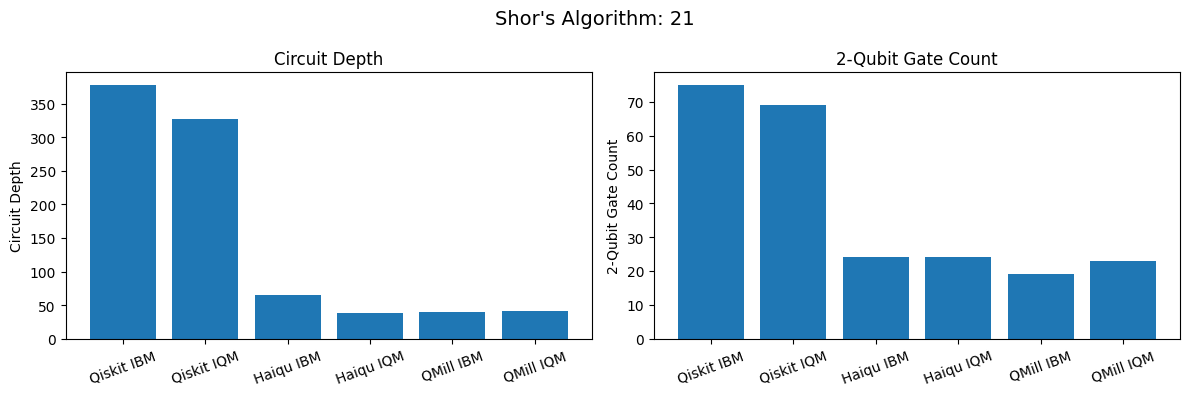
Shor’s Algorithm: Factoring 21
I did not have this circuit in my library, so I used the circuit in “Demonstration of Shor’s factoring algorithm for N= 21 on IBM quantum processors.” Notwithstanding that it uses a compiled version of QPE using relative phase shift Toffoli gates, it was the easiest-to-find example of factoring 21 with Shor’s algorithm, and it’s still a hefty circuit.
The primary reason why I’m including it is because it is showing my original prediction for this article, which is that Haiqu might excel with some circuits while QMill might excel with others. I’ve encountered that before, where the “winner” is not necessarily universal. In this case, even with the paper’s authors making the circuit as svelte as they possibly could, Haiqu and QMill both improved upon it, with QMill slightly edging out Haiqu when compressing for IBM, and with mixed results when compressing for IQM; the former had a slightly lower two-qubit gate count while the latter had slightly less depth.
That said, QMill’s circuit once again fared poorly on IQM Emerald, and there are once again multiple potential reasons for that. Haiqu’s circuit executed well on ibm_kingston, so Round 2 will have to use QMill’s IBM Heron circuit for an oranges-to-oranges comparison.
Other Observations
These will affect different users differently:
Getting all 3 products to work in one environment was fun, in the most sarcastic sense of the word. Kids, don’t try this at home.
Accounts matter. I used my IBM Quantum and IQM Resonance accounts, but I don’t have an AWS account. What you have will affect what’s accessible to you.
There may be a point of diminishing returns, where you can use the LUMI supercomputer to compress QMill’s circuits with 4 GPUs for 6 hours, but the gains probably stop much earlier than that. With Grover’s algorithm, just looking at the histogram, there wasn’t a noticeable difference between running QMill for 1 minute, 30 minutes, or 6 hours.
Conclusion
As someone who writes for a living, I really ought to be more eloquent than the word “WOW!” would indicate, but I submit to you that it is fully descriptive of Haiqu’s quantum circuit compression software. I was impressed when Grover’s algorithm executed on ibm_kingston, but I was blown away when it handled QPE.
Nevertheless, QMill is a worthy competitor. It also demonstrated that it could execute a toy example of an FTQC algorithm (Grover’s algorithm) on NISQ hardware and retrieve the correct results. It also demonstrated that it can, as I suspected, eke out a numerical win, as it did with factoring 21 with Shor’s algorithm. Furthermore, let the record show that QMill allows you to consume the free credits that you can get from both IBM Quantum and IQM Resonance, and then might be worthy of your consideration.
Round 1 was a battle of quantity over quality, so Round 2 will take a closer look at the results.
Epilogue
As this article was queued up for publication, Haiqu launched a new academic program. If you’re a researcher, you can apply for free access to the platform.
Image generated by OpenAI’s DALL·E and Google’s language model AI.